Regularised RL Improves Sim-to-Real Transfer
Preprint
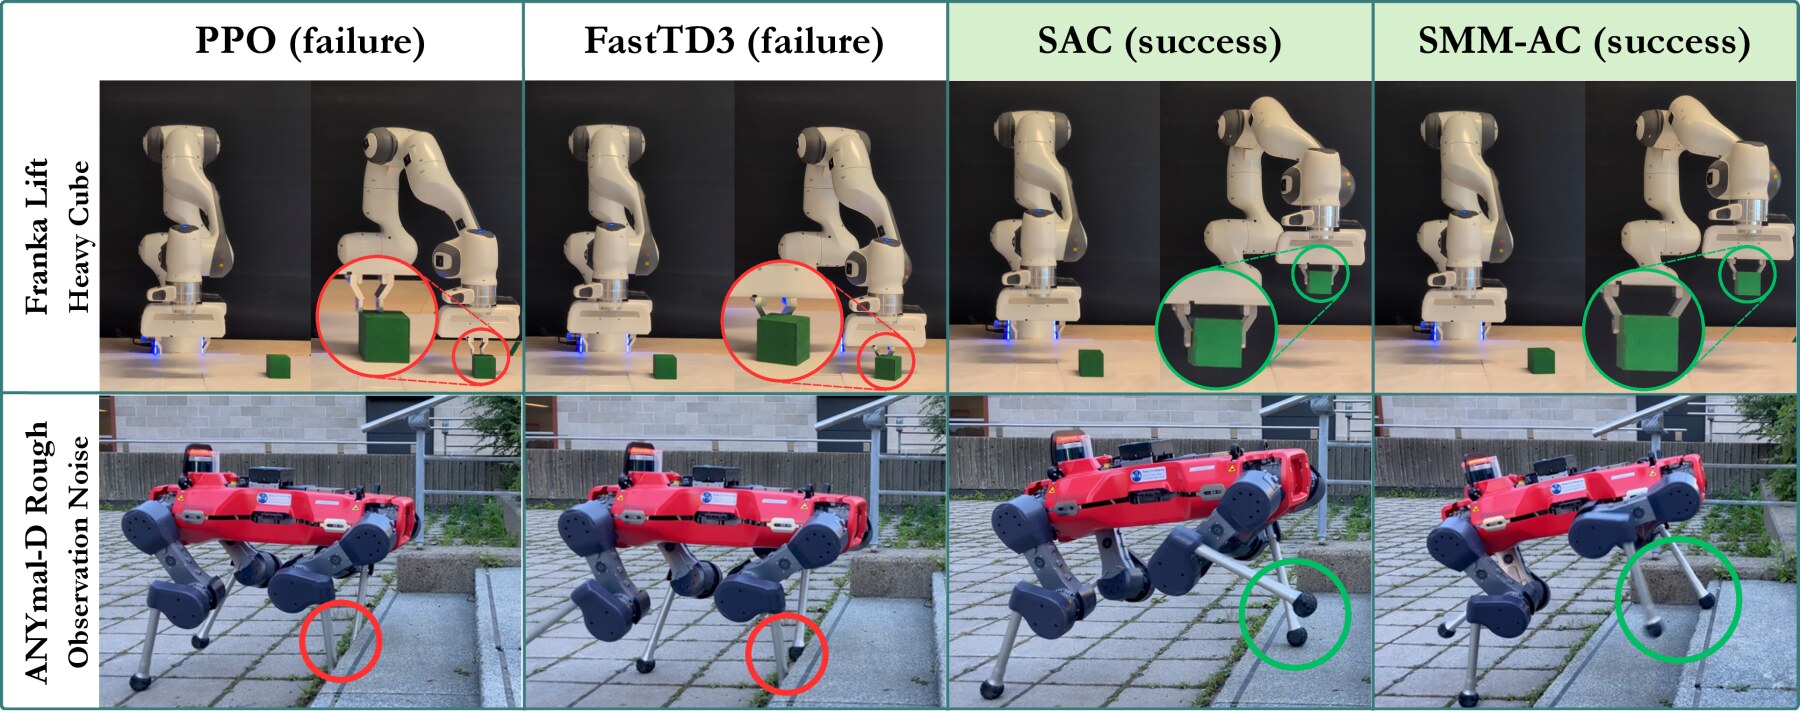
Regularised RL has long promised robustness guarantees, but weakly regularised algorithms like PPO still dominate sim-to-real pipelines. We derive SMM-AC, a continuous-control actor-critic built on the soft mellowmax value function, and show on a Franka arm and an ANYmal-D quadruped that regularisation translates into real sim-to-real gains.